

毎月、GOWUKAKUは1500人以上の受験者が試験準備を助けて、試験に合格するために受験者にご協力します
Hadoop 2.0 Certification exam for Pig and Hive Developer 試験
最新更新時間: 2026/09/21
【秋学習応援セール|10月限定キャンペーン】:Apache Hadoop Developer 最新真題を買う時、日本語版と英語版両方を同時に獲得できます。
実際の問題集を練習し、試験のポイントを了解し、テストに申し込むするかどうかを決めることができます。
さらに試験準備時間の35%を節約するには、Apache Hadoop Developer 問題集を使用してください。
Question No : 1
In the reducer, the MapReduce API provides you with an iterator over Writable values.
What does calling the next () method return?
正解:
Explanation:
Calling Iterator.next() will always return the SAME EXACT instance of IntWritable, with the contents of that instance replaced with the next value.
Reference: manupulating iterator in mapreduce
Question No : 2
In Hadoop 2.0, which one of the following statements is true about a standby NameNode?
The Standby NameNode:
正解:
Question No : 3
You write MapReduce job to process 100 files in HDFS. Your MapReduce algorithm uses TextInputFormat: the mapper applies a regular expression over input values and emits key-values pairs with the key consisting of the matching text, and the value containing the filename and byte offset. Determine the difference between setting the number of reduces to one and settings the number of reducers to zero.
正解:
Explanation:
* It is legal to set the number of reduce-tasks to zero if no reduction is desired.
In this case the outputs of the map-tasks go directly to the FileSystem, into the output path set by setOutputPath(Path). The framework does not sort the map-outputs before writing them out to the FileSystem.
* Often, you may want to process input data using a map function only. To do this, simply set mapreduce.job.reduces to zero. The MapReduce framework will not create any reducer tasks. Rather, the outputs of the mapper tasks will be the final output of the job.
Note:
Reduce
In this phase the reduce(WritableComparable, Iterator, OutputCollector, Reporter) method is called for each <key, (list of values)> pair in the grouped inputs.
The output of the reduce task is typically written to the FileSystem via OutputCollector.collect(WritableComparable, Writable).
Applications can use the Reporter to report progress, set application-level status messages and update Counters, or just indicate that they are alive.
The output of the Reducer is not sorted.
Question No : 4
For each input key-value pair, mappers can emit:
正解:
Explanation:
Mapper maps input key/value pairs to a set of intermediate key/value pairs.
Maps are the individual tasks that transform input records into intermediate records. The transformed intermediate records do not need to be of the same type as the input records. A given input pair may map to zero or many output pairs.
Reference: Hadoop Map-Reduce Tutorial
Question No : 5
Which describes how a client reads a file from HDFS?
正解:
Explanation:
Reference: 24 Interview Questions & Answers for Hadoop MapReduce developers, How the Client communicates with HDFS?
Question No : 6
In a MapReduce job, the reducer receives all values associated with same key.
Which statement best describes the ordering of these values?
正解:
Explanation:
Note:
* Input to the Reducer is the sorted output of the mappers.
* The framework calls the application's Reduce function once for each unique key in the sorted order.
* Example:
For the given sample input the first map emits:
< Hello, 1>
< World, 1>
< Bye, 1>
< World, 1>
The second map emits:
< Hello, 1>
< Hadoop, 1>
< Goodbye, 1>
< Hadoop, 1>
Question No : 7
Given the following Hive commands:
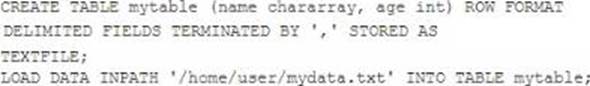
Which one of the following statements Is true?
正解:
Question No : 8
Consider the following two relations, A and B.
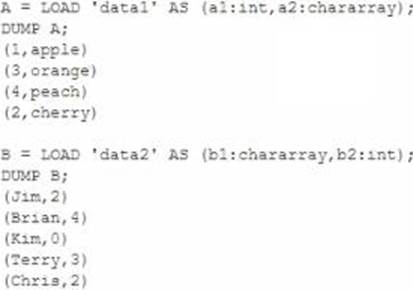
正解:
Question No : 9
Given the following Pig command:
logevents = LOAD 'input/my.log' AS (date:chararray, levehstring, code:int, message:string);
Which one of the following statements is true?
正解:
Question No : 10
Which one of the following Hive commands uses an HCatalog table named x?
正解:
Question No : 11
You are developing a combiner that takes as input Text keys, IntWritable values, and emits Text keys, IntWritable values.
Which interface should your class implement?
正解:
Question No : 12
Which one of the following statements regarding the components of YARN is FALSE?
正解:
Question No : 13
You need to create a job that does frequency analysis on input data. You will do this by writing a Mapper that uses TextInputFormat and splits each value (a line of text from an input file) into individual characters. For each one of these characters, you will emit the character as a key and an InputWritable as the value.
As this will produce proportionally more intermediate data than input data, which two resources should you expect to be bottlenecks?
正解:
Question No : 14
What types of algorithms are difficult to express in MapReduce v1 (MRv1)?
正解:
Explanation:
See 3) below.
Limitations of Mapreduce C where not to use Mapreduce
While very powerful and applicable to a wide variety of problems, MapReduce is not the answer to every problem. Here are some problems I found where MapReudce is not suited and some papers that address the limitations of MapReuce.
Question No : 15
What does Pig provide to the overall Hadoop solution?
正解: